Stage 1 — LLM Basics
LLM (Large Language Model): a model that reads and writes language.
Purpose: first see how a model moves from data to an Agent, then use a repeatable local-to-cloud path to call an LLM through an API (application programming interface). You will understand Token, Context Window, and Temperature, and explain model choices using cost and latency.
📌 Learning Goals
By the end of this stage, you can:
- Make your first API call with a local Ollama model, then compare it with Anthropic.
- Explain the order from Pre-training and Post-training to Inference.
- Explain token, context window, and temperature with simple examples.
- Read input and output token counts from a response's
usagefield. - Explain a model choice using input/output price, latency, and data sensitivity.
Three Core Terms
1. Token
A Token is a unit a model reads and writes; APIs often charge by token. Think of a sentence cut into small blocks: a word may be one block or several, and one Chinese character is not always one block. In Exercise 2, read actual input/output token counts to estimate cost. Character counts are not exact because tokenizers (text-splitting tools) differ.
2. Context Window
A Context Window is the token space for one request. Think of a desk: instructions, data, and chat history take space, and the model needs room for its answer. The maximum-output limit may be smaller, so check both numbers. Use them to decide when to trim, summarize, or split a long document.
3. Temperature
Temperature controls how much sampling varies. Imagine choosing the next block from several candidates: a low value favors the most likely candidate, which suits classification and fixed formats; a high value tries less likely candidates more often, which can help brainstorming but may be less stable. This stage treats it as a knob for output stability; it does not add knowledge or guarantee exact reproducibility.
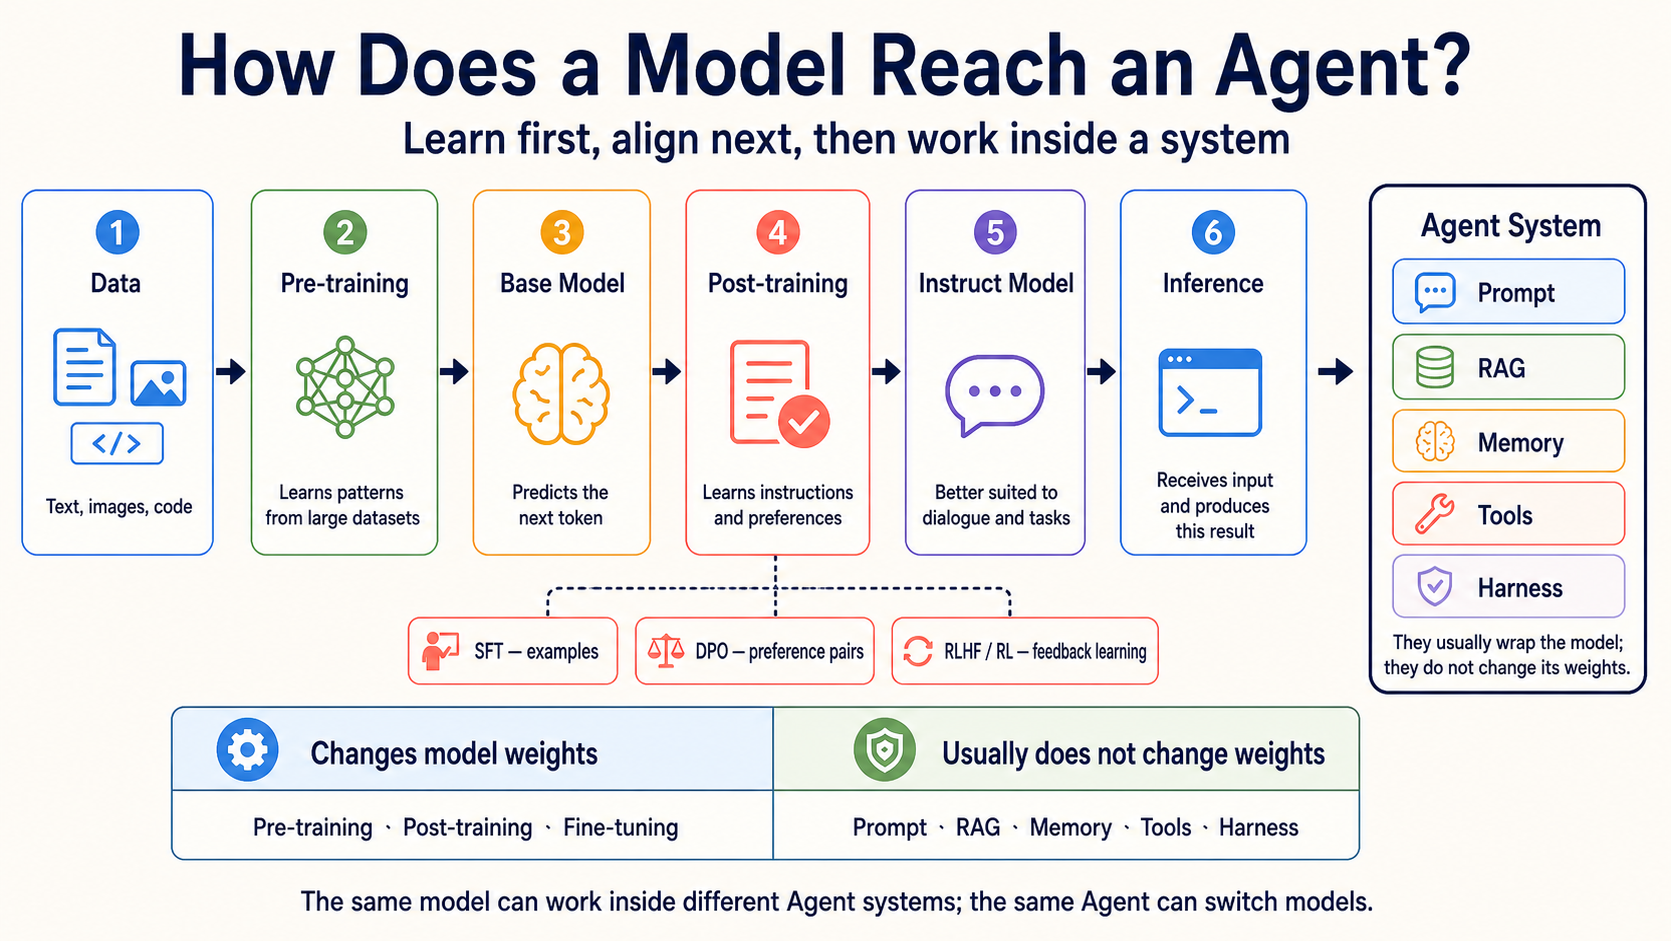
How a Model Moves from Data to an Agent
- Pre-training: the model learns patterns from large amounts of text, images, or code. This changes model weights, the values learned inside the model.
- Base Model: a pretrained model that learns to continue content; it may not yet follow instructions.
- Post-training: demonstrations, preferences, or feedback teach the model to follow instructions and act more safely. This also changes weights. Common methods include:
- SFT (Supervised Fine-Tuning): teach the model to imitate good inputs and answers.
- DPO (Direct Preference Optimization): teach preferences using pairs of better and worse answers.
- RLHF (Reinforcement Learning from Human Feedback): use human feedback in reinforcement learning.
- RL (Reinforcement Learning): learn from rewards, which can also come from rules.
- Instruct Model: a model further adapted to follow instructions.
- Fine-tuning: smaller, specialized data is used to continue changing model weights. Post-training is the broad later-training stage; Fine-tuning is one common kind of it.
- Inference: after training, the model receives one input and produces one result. This uses the model; it does not retrain it.
RAG (Retrieval-Augmented Generation): retrieve relevant material, then answer using it.
An Agent is not the next model version. At runtime it uses a model to choose the next step, and may use RAG and these parts to complete work. These parts usually do not change model weights.
- Prompt: tells the model the task and rules.
- Memory: saves information for later use.
- Tools: let the system find information or take actions.
- Harness: manages tools, rules, and stopping conditions.
Data → Pre-training → Base Model → Post-training → Instruct Model → Inference → Agent system
The next three methods are advanced electives; beginners only need to recognize their names:
- GRPO (Group Relative Policy Optimization): compare several answers to the same question and learn from their relative results.
- LoRA (Low-Rank Adaptation): freeze the original weights and train added low-rank matrices.
- PEFT (Parameter-Efficient Fine-Tuning): a group of methods that trains fewer parameters.
To compare Distillation (learning from another model) and Quantization (reducing numerical precision), open the optional model training and adaptation guide. Beginners do not need to train a model in this stage.
Scene-Based Model Picker
A Typed Decision Model returns a predefined choice, score, or probability. TypeSafe AI's Jev is one; it cannot chat, summarize, or write code.
Deciding is not authorization: code must check permissions; ask a person before sending mail, paying, or deleting files.
| Your situation | Start with | Why |
|---|---|---|
| Learning the API and iterating at zero cost | Ollama + gemma4:e4b |
Runs locally, so each API call costs $0 and the example can be repeated freely. |
| Comparing cloud quality when data may be sent out | Claude Haiku 5.5 / Sonnet 5.5 | The Anthropic SDK (Software Development Kit, a toolkit of developer tools and libraries) path is simple; pricing is based on input and output tokens. |
| OpenAI Agent API | GPT-6.1 Sol / Terra / GPT-6 Luna | Sol for coding; Terra for images and writing; Luna for simple tasks. Test first; check pricing. |
| Very long documents with images or video | Gemini 3.8 Flash or Kimi K3.1 Pro | Check context and multimodal support; test with your document. |
| Chinese-language API work with usage control | DeepSeek V4.1 Flash or GLM-5.3 | Compare official prices, output limits, and availability; do not choose by name alone. |
| Classification, scoring, or routing with fixed choices that code will use directly | Jev 1.13 (service in early access) | Returns probabilities for Choice, Score, or Noul questions; send low-confidence or high-risk actions to a person or another model. |
| Privacy, offline use, or self-hosting | Llama 4, Qwen 3.8, Gemma 4, and other open weights | Estimate hardware and license requirements, then measure real speed with Ollama or another runtime. |
Gemini 4 Carbon has been announced, but it is not yet available to general developers. Google is gradually opening access to selected teams that protect computer systems and trusted partners. Start with an available model; see the official announcement.
Haiku 5.5 (released 2026-10-07; checked 2026-10-08) suits classification, summarization, and narrowly scoped subagents; evaluate Sonnet/Opus for complex coding agents. Its fixed API ID is claude-haiku-5-5, without a date suffix or separate alias. Exercises 1 and 3 use 5.5; the temperature exercise and cross-stage examples retain a Haiku 4.5 compatibility baseline. With adaptive thinking enabled by default, select text by block type, preserve thinking blocks, and recount tokens; an ID-only swap is insufficient. See the announcement and Haiku 5.5 migration guide.
🚪 Entry Conditions
The main path uses local Ollama; before starting, check only your time, tools, and budget.
🧭 Expand time, prerequisites, environment, and budget
Time and prerequisites
Allow about one week and 5–8 hours. You should be able to run a Python script and understand HTTP/REST at a basic level. An API key is not required for the main path because the exercises use local Ollama. If Python or the command line is still unfamiliar, return to Stage 0.
Environment
Path A needs Ollama, pip install openai, and ollama pull gemma4:e4b. On a low-memory machine, use gemma4:e2b. Tool-use exercises from Stage 3 onward use qwen2.5:3b; do not mix that tag into the chat examples here. Path B needs pip install anthropic and ANTHROPIC_API_KEY.
Budget
The local path costs $0 per call (though it uses electricity and time). For 3–5 runs per exercise, cloud totals vary with prompt length and model; calculate each call from its usage, then multiply by the planned count. Each exercise below gives both a per-call reminder and a stage-budget method; these are teaching estimates, not billing guarantees.
📚 Required Reading
Know where these seven official entry points are; open them when needed instead of reading everything first.
Read 1–3 before starting the exercises; consult 4–7 when you need model, tokenizer, or local-runtime details:
- OpenAI: how models are developed — the relationship between data, training, and models.
- Google Machine Learning: LLM tuning — the boundary between Prompt Engineering, Fine-tuning, and Distillation.
- Anthropic Claude model overview — model names, context, and pricing entry point.
- OpenAI API models — model and pricing fields.
- Google Gemini models — GA/Preview status and context.
- Hugging Face LLM Course: Tokenizers — how tokenizers split text.
- Ollama — installing and serving local models.
🛠 Hands-On Exercises
Exercise 1: LLM API (hello world)
Outcome: Make a short core call, receive a response, and read output tokens from usage. Per-call budget: Ollama $0; Anthropic Haiku: calculate from this call's input/output usage and the 5.5 rates of $0.10/$0.50 for prompts up to 100K tokens ($0.50/$2.50 above 100K). Stage budget: local runs remain $0; add the actual usage from 3–5 cloud runs.
📋 Starter — Path A (local Ollama gemma4:e4b, default) (copy to practice_1.py and run python practice_1.py)
# Requires: pip install openai      (use the OpenAI-compatible SDK with Ollama)
# Before running: ollama pull gemma4:e4b && ollama serve
import sys
if hasattr(sys.stdout, "reconfigure"):
    sys.stdout.reconfigure(encoding="utf-8", errors="replace")

from openai import OpenAI

client = OpenAI(
    base_url="http://localhost:11434/v1",
    api_key="ollama",  # Ollama does not validate this placeholder
)

r = client.chat.completions.create(
    model="gemma4:e4b",
    max_tokens=100,
    reasoning_effort="none",
    messages=[{"role": "user", "content": "Introduce yourself in one sentence."}],
)

# === Self-check ===
choice = r.choices[0]
text = choice.message.content or ""
print("Response:", text)
print("usage:", r.usage)

assert choice.finish_reason == "stop" and text.strip(), f"Expected complete non-empty response; got finish_reason={choice.finish_reason!r}"
assert r.usage.completion_tokens > 0, "Output tokens must be greater than zero"
print("✅ Exercise 1 passed — Ollama gemma4:e4b answered locally at $0 per call")
📋 Starter — Path B (Anthropic API, optional) (copy to practice_1_anthropic.py)
# Requires: pip install anthropic
# Environment variable: export ANTHROPIC_API_KEY=sk-ant-...
import sys
if hasattr(sys.stdout, "reconfigure"):
    sys.stdout.reconfigure(encoding="utf-8", errors="replace")

import anthropic

client = anthropic.Anthropic()
msg = client.messages.create(
    model="claude-haiku-5-5",
    max_tokens=4096,
    output_config={"effort": "low"},
    messages=[{"role": "user", "content": "Introduce yourself in one sentence."}],
)

# === Self-check ===
text = "".join(block.text for block in msg.content if block.type == "text")
print("Response:", text)
print("usage:", msg.usage)

assert msg.stop_reason in ("end_turn", "max_tokens"), f"Unexpected stop_reason: {msg.stop_reason}"
assert len(text) > 0, "The response must not be empty"
assert msg.usage.input_tokens > 0 and msg.usage.output_tokens > 0, "Token counts must be greater than zero"
print("✅ Exercise 1 passed — the Anthropic API call succeeded")
Exercise 2: Tokens
Outcome: Repeat one prompt and observe how language, temperature, and output length affect token use. Per-call budget: Ollama $0; Anthropic Haiku: calculate from that call's input/output usage and official rates. Stage budget: local is $0; add the actual usage from 3–5 repeated Path B tests.
📋 Starter — Path A (local Ollama gemma4:e4b, default) (copy to practice_2.py)
# Requires: pip install openai     (use the OpenAI-compatible SDK with Ollama)
# Before running: ollama pull gemma4:e4b && ollama serve
import sys, statistics
if hasattr(sys.stdout, "reconfigure"):
    sys.stdout.reconfigure(encoding="utf-8", errors="replace")

from openai import OpenAI

client = OpenAI(base_url="http://localhost:11434/v1", api_key="ollama")

PROMPTS = {
    "Chinese": "用一句話描述一隻貓在做什麼。",
    "English": "Describe in one sentence what a cat is doing.",
}

N = 10  # Keep N small on a slow computer; increase it after this works
for label, prompt in PROMPTS.items():
    output_tokens = []
    for _ in range(N):
        r = client.chat.completions.create(
            model="gemma4:e4b",
            max_tokens=80,
            reasoning_effort="none",
            temperature=1.0,  # Raise temperature to observe variation
            messages=[{"role": "user", "content": prompt}],
        )
        choice = r.choices[0]
        text = choice.message.content or ""
        assert choice.finish_reason == "stop" and text.strip(), f"Discard incomplete/empty output (finish_reason={choice.finish_reason!r})"
        output_tokens.append(r.usage.completion_tokens)
    print(f"\n[{label}] prompt: {prompt}")
    print(f"  input tokens: {r.usage.prompt_tokens}")
    print(f"  output tokens — min={min(output_tokens)} max={max(output_tokens)} mean={statistics.mean(output_tokens):.1f} stdev={statistics.stdev(output_tokens):.1f}")

# === Self-check ===
assert len(output_tokens) == N and all(n > 0 for n in output_tokens), "Every output token count must be nonzero"
print("\n✅ Exercise 2 passed — output tokens were observed for two languages at $0 locally")
print("💡 Token counts depend on the tokenizer and actual content. Do not estimate them only from character counts or assume one language always uses more.")
📋 Starter — Path B (Anthropic API, optional) (copy to practice_2_anthropic.py)
# Requires: pip install anthropic
import sys, statistics
if hasattr(sys.stdout, "reconfigure"):
    sys.stdout.reconfigure(encoding="utf-8", errors="replace")

import anthropic

client = anthropic.Anthropic()
PROMPTS = {"Chinese": "用一句話描述一隻貓在做什麼。", "English": "Describe in one sentence what a cat is doing."}

for label, prompt in PROMPTS.items():
    output_tokens = []
    for _ in range(20):
        msg = client.messages.create(model="claude-haiku-4-5", max_tokens=80, temperature=1.0,
                                     messages=[{"role": "user", "content": prompt}])
        output_tokens.append(msg.usage.output_tokens)
    print(f"[{label}] input={msg.usage.input_tokens} output min/max/mean={min(output_tokens)}/{max(output_tokens)}/{sum(output_tokens)/len(output_tokens):.1f}")
The Anthropic call uses client.messages.create(), usage.input_tokens, and content blocks, which differ from the OpenAI-compatible fields in Ollama. Calculate the call's cost from its returned token counts.
Exercise 3: Pricing / Latency
Outcome: Measure token cost and waiting time separately for the same small task. Per-call budget: Ollama $0; Anthropic Haiku: calculate from this call's input/output usage and official rates. Stage budget: local is $0; for Path B, run once to get actual counts, then multiply by your planned count.
📋 Starter — Path A (local Ollama gemma4:e4b, measure latency) (copy to practice_3.py)
# Requires: pip install openai
# Before running: ollama pull gemma4:e4b && ollama serve
import sys, time
if hasattr(sys.stdout, "reconfigure"):
    sys.stdout.reconfigure(encoding="utf-8", errors="replace")

from openai import OpenAI

client = OpenAI(base_url="http://localhost:11434/v1", api_key="ollama")

# Measure latency and output tokens five times
latencies = []
output_tokens = []
for _ in range(5):
    t0 = time.time()
    r = client.chat.completions.create(
        model="gemma4:e4b",
        max_tokens=200,
        messages=[{"role": "user", "content": "Hello! Please introduce yourself."}],
    )
    latencies.append(time.time() - t0)
    output_tokens.append(r.usage.completion_tokens)

# Summary statistics
avg_latency = sum(latencies) / len(latencies)
out_tok_avg = sum(output_tokens) / len(output_tokens)  # five-run average
tps = out_tok_avg / avg_latency if avg_latency > 0 else 0

print(f"model: gemma4:e4b (local)")
print(f"5-run latency (sec): min={min(latencies):.2f} max={max(latencies):.2f} mean={avg_latency:.2f}")
print(f"avg output: {out_tok_avg} tokens, about {tps:.1f} tokens/sec")
print(f"\n1000-call cost: $0 (local); estimated time: {avg_latency * 1000 / 60:.1f} minutes")

# === Self-check ===
assert avg_latency > 0, "Latency must be greater than zero"
assert out_tok_avg > 0, "Output tokens must be greater than zero"
print(f"\n✅ Exercise 3 passed — the local model costs $0 per call but needs about {avg_latency * 1000 / 60:.0f} minutes for 1000 calls")
print("💡 For Anthropic Path B, estimate 1000-call cost from actual input/output usage and official rates, then compare it with local waiting time.")
📋 Starter — Path B (Anthropic API, calculate cost) (copy to practice_3_anthropic.py)
# Requires: pip install anthropic
import sys
if hasattr(sys.stdout, "reconfigure"):
    sys.stdout.reconfigure(encoding="utf-8", errors="replace")

import anthropic

# Anthropic public pricing (USD per 1M tokens) — recheck before running: https://www.anthropic.com/pricing
PRICING = {
    "claude-haiku-5-5":   {"input": 0.10, "output":  0.50},
    "claude-sonnet-5-5":  {"input": 2.00, "output": 10.00},
    "claude-opus-5-5":    {"input": 4.00, "output": 20.00},
    "claude-fable-5-1":   {"input": 10.00, "output": 50.00},
}

def rates_for(model, input_tokens):
    if model == "claude-haiku-5-5" and input_tokens > 100_000:
        return {"input": 0.50, "output": 2.50}
    return PRICING[model]

client = anthropic.Anthropic()
MODEL = "claude-haiku-5-5"

msg = client.messages.create(model=MODEL, max_tokens=4096,
                             output_config={"effort": "low"},
                             messages=[{"role": "user", "content": "Hello! Please introduce yourself."}])
in_tok, out_tok = msg.usage.input_tokens, msg.usage.output_tokens
rates = rates_for(MODEL, in_tok)
cost_one = (in_tok * rates["input"] + out_tok * rates["output"]) / 1_000_000

print(f"model: {MODEL}")
print(f"single: input={in_tok} output={out_tok} → ${cost_one:.6f}")
print("1000-call rate-only illustration (not measured cross-model costs):")
for name in PRICING:
    r = rates_for(name, in_tok)
    c = (in_tok * r["input"] + out_tok * r["output"]) / 1_000_000 * 1000
    print(f"  {name:<22} ${c:.4f}")

# === Self-check ===
assert cost_one > 0, "A cloud LLM call must have a positive cost"
print(f"\n✅ Exercise 3 passed (Anthropic) — this call is costed; cross-model figures compare rates only and require fresh token measurements")
🎯 Curated Projects
Recommended Capstone: Personal document-summary cost/quality comparer
Build a small command-line tool that reads 3–5 text passages you are allowed to use, summarizes them with Ollama and one Anthropic model, records input/output tokens, latency, and estimated cost, and uses a fixed checklist to mark omitted facts. It connects this stage's three core terms and model picker without requiring RAG or an agent.
📦 Capstone acceptance checklist and other project entries
The finished project should show:
- Both paths and model names for the same input.
- Input/output tokens, latency, and per-call cost for each call.
- A fixed quality checklist rather than a purely subjective choice.
- When to use local versus cloud, and how to batch when context is insufficient.
The table below keeps the 17 original extension entries. They are optional, not required work. A recommendation is an editorial judgment, not GitHub popularity: ⭐⭐⭐⭐⭐ means skipping it would block the stage. Because every entry here is supplementary, the table honestly uses ⭐⭐⭐⭐, ⭐⭐⭐, or ⭐⭐ for historical reference and omits volatile star counts.
| Category | Resource | Link | Recommendation | Use / status |
|---|---|---|---|---|
| Official API intro | Anthropic Cookbook | GitHub | ⭐⭐⭐⭐ | Claude API notebooks for tool use, batch, and prompt cache. |
| Anthropic Courses | GitHub | ⭐⭐⭐⭐ | Archived official courses: read older examples, then check the current API Quickstart below before building. | |
| OpenAI Cookbook | GitHub | ⭐⭐⭐⭐ | OpenAI API, structured output, and function-calling examples. | |
| Anthropic Claude API Quickstart | Docs | ⭐⭐⭐ | Quick path to a first Claude API call. | |
| Chinese learning | datawhalechina/happy-llm | GitHub | ⭐⭐⭐⭐ | Understand LLM principles and training in Chinese. |
| datawhalechina/llm-universe | GitHub | ⭐⭐⭐⭐ | Extends from API basics to knowledge bases and RAG. | |
| datawhalechina/llm-cookbook | GitHub | ⭐⭐⭐ | Chinese adaptation of an Andrew Ng course; updates are slower. | |
| jingyaogong/minimind | GitHub | ⭐⭐⭐ | Implement a small model from scratch; Apache-2.0. | |
| English course | Hugging Face — LLM Course | Course | ⭐⭐⭐⭐ | Transformers, tokenizers, and the Hugging Face ecosystem. |
| LangChain Academy | Course | ⭐⭐⭐ | Official free course including RAG and agents. | |
| Local runtime | ollama/ollama | GitHub | ⭐⭐⭐⭐ | Local runtime used by this stage's Path A. |
| ggml-org/llama.cpp | GitHub | ⭐⭐⭐⭐ | Understand quantization and the local inference layer. | |
| mudler/LocalAI | GitHub | ⭐⭐⭐ | OpenAI-compatible self-hosted service. | |
| ml-explore/mlx | GitHub | ⭐⭐⭐ | Machine-learning framework for Apple Silicon. | |
| From-scratch | Karpathy — Let's build GPT from scratch | Video | ⭐⭐⭐⭐ | Build a GPT from scratch with PyTorch. |
| rasbt/LLMs-from-scratch | GitHub | ⭐⭐⭐⭐ | Work through tokenizers, attention, and training with code. | |
| karpathy/LLM101n | GitHub | ⭐⭐ | Archived course outline; historical reference, not current teaching. |
Other projects (by difficulty)
- Beginner: multilingual token counter, one-sentence summarizer, temperature comparison sheet.
- Intermediate: cross-provider prompt evaluator, retry wrapper, local-model latency dashboard.
- Extension: batched document summarizer, configurable model router, privacy-focused local inference service.
Exercise 4: Cross-Provider Comparison
Outcome: Compare providers on one prompt and record differences without treating one run as a ranking. Per-call budget: Path A Ollama $0; Path B uses each provider's actual token pricing. Stage budget: local is $0; run one cloud call per provider first, then estimate 3–5 evaluation sets.
🔬 Exercise 4 details (optional)
- Path A (Ollama, main practice): Use the Ollama call in
examples/stage-1/04-cross-provider/as the local baseline. - Path B (Anthropic, optional): Add the Anthropic SDK to the same dataset; if you add OpenAI or Google too, record model, parameters, tokens, and failures for each.
- Compare style, length, format adherence, and omitted facts. Treat this as a small task evaluation, not an official specification or universal ranking.
The starter runs three SDKs in parallel and skips providers without keys. It is illustrative, not a chapter-length tutorial.
Exercise 5: Error Handling
Outcome: Write a testable flow for classifying errors, retrying, and stopping. Per-call budget: Path A Ollama $0; Path B costs nothing when it uses mocks. Stage budget: local and mock tests are $0; if you add a cloud integration test, limit it to 1–2 calls and add actual token costs.
🧰 Exercise 5 details (optional)
- Path A (Ollama, main practice): Run the mock-based tests in
examples/stage-1/05-error-handling/first, then observe recoverable network errors against the local endpoint. - Path B (Anthropic, optional): Attach Anthropic exception types to the same retry wrapper; invalid keys and overlong contexts must not retry forever.
- Cover an invalid key, an overlong prompt, and a network interruption. Give exponential backoff a cap and a clear maximum attempt count.
The starter verifies retry logic without actually disconnecting the network. It is illustrative, not a chapter-length tutorial.
Exercise 6: Local LLM
Outcome: Start Ollama locally and call a local model through an OpenAI-compatible API. Per-call budget: Ollama $0 (plus hardware electricity); Path B uses actual cloud token pricing. Stage budget: local is $0; if you make one Anthropic quality comparison, limit it to 1–3 calls and record usage.
🦙 Exercise 6 details (optional)
Path A (Ollama, main runnable path):
# 1. Install Ollama: https://ollama.com
ollama pull qwen2.5:3b
ollama serve  # default port: 11434
# Requires: pip install openai
# Before running: Ollama is serving and qwen2.5:3b is installed
import sys
if hasattr(sys.stdout, "reconfigure"):
    sys.stdout.reconfigure(encoding="utf-8", errors="replace")

from openai import OpenAI

client = OpenAI(
    base_url="http://localhost:11434/v1",
    api_key="ollama",  # Ollama does not validate this placeholder
)

r = client.chat.completions.create(
    model="qwen2.5:3b",
    messages=[{"role": "user", "content": "Explain ReAct in three sentences."}],
)

text = r.choices[0].message.content
print("Response:", text)

# === Self-check ===
assert len(text) > 10, "The response is too short; Ollama may not be running"
print("✅ Exercise 6 passed — local Ollama responded through an OpenAI-compatible API")
print("💡 This call cost $0, apart from your electricity")
Path B (Anthropic, optional): Send the same ReAct prompt to claude-haiku-4-5, save the response and msg.usage, then compare format adherence, latency, and cost with Path A. Do not treat the cloud result as a specification guarantee for the local model.
Without Ollama, replace base_url with LM Studio (http://localhost:1234/v1) or a vLLM endpoint. The interface is similar, but model tags and hardware requirements must be checked again.
🌐 Complete 18-family table (official specification entries)
Full table checked: 2026-09-22 UTC. Scoped GPT/Kimi update: 2026-10-26 UTC. Claude row updated: 2026-10-08 UTC. Gemini row updated: 2026-10-29 UTC. Muse/Mistral/Jev and GPT electives updated: 2026-10-15 UTC. DeepSeek/Decisions/Clef electives updated: 2026-10-23 UTC.
If an official source gives no reliable public number, the table says “Not published by the official source.” Prices use USD per 1M tokens unless the provider uses another unit. Cache is like reusing a note you already read: reading old content and writing new content may have different prices.
Open the family you need, then check its models, pricing, and limits.
Claude
| Field | Details |
|---|---|
| Models | Fable 5.1 (claude-fable-5-1) |
Mythos 5.1 (claude-mythos-5-1) | |
Opus 5.5 (claude-opus-5-5) | |
Sonnet 5.5 (claude-sonnet-5-5) | |
Haiku 5.5 (claude-haiku-5-5) | |
| Status | Fable/Opus/Sonnet/Haiku: generally available; Mythos: vetted access only |
| Context | 1M context / 128K max output |
| Price or license | Claude API: Fable/Mythos US$10/$50, Opus US$4/$20, Sonnet US$2/$10, Haiku US$0.10/$0.50 (prompt ≤100K), US$0.50/$2.50 (prompt >100K) per million input/output tokens; Sonnet cache read US$0.10, Opus US$0.20, Fable/Mythos US$0.25 |
| Good for | Long-form, coding, long-running agent workflows |
| Limits | Mythos 5.1 is limited to vetted cybersecurity and life-science users; Sonnet 5.5 changes forced tool choice and temperature settings, so read the migration guide before upgrading existing code; cloud-partner prices differ |
| Official source | Claude model overview · Opus 5.5 · Sonnet 5.5 · Migration guide · Haiku 5.5 · Haiku 5.5 migration · Claude API pricing |
GPT
| Field | Details |
|---|---|
| Models | GPT-6 Astra (gpt-6-astra) |
GPT-6.1 Sol (gpt-6.1-sol) | |
GPT-6.1 Terra (gpt-6.1-terra) | |
GPT-6 Luna (gpt-6-luna) | |
| Status | Generally available API models; the Free tier is not supported |
| Context | 1.05M context / 128K max output |
| Price or license | Standard API, US$ per 1M tokens, input/cache read/cache write (30 minutes)/output. |
| Astra $10/$1/$12.50/$50. | |
| Sol 6.1 $2/$0.10/$2.50/$10. | |
| Terra 6.1 $1/$0.05/$1.25/$5; 12-hour cache writes $2.50. | |
| Luna $0.10/$0.01/$0.125/$0.50. | |
| Good for | Sol 6.1 for coding and multi-step Agent work. Terra 6.1 for images, screen actions and rewriting. Luna for focused, repeated tasks. Evaluate Astra's cost-quality tradeoff on your own tasks. |
| Limits | Sol 6.1 and Terra 6.1 tool calling requires Responses API; Chat Completions has no tool calling. Above 272K input, the full request uses 2× input/cache and 1.5× output rates. Batch/Flex are half-price, Fast is 2×. Tools may cost extra. |
| Official source | GPT-6 Astra · GPT-6.1 Sol · GPT-6.1 Terra · GPT-6 Luna · OpenAI API pricing |
Jev (TypeSafe AI)
| Field | Details |
|---|---|
| Models | TypeSafe direct: stable Jev 1.13 (jev-1.13.0 / jev-latest) |
Preview Jev 1.14 (jev-1.14.0 / jev-preview) | |
Cloudflare route: typesafe/jev | |
| Status | 1.13: official model; 1.14: Preview. Service remains in early access |
| Context | TypeSafe direct: 64K per request, 32K for state plus the longest question. Cloudflare route: 32K |
| Price or license | TypeSafe direct: US$0.042 per million input tokens, output is unmetered. Cloudflare route: see the Cloudflare dashboard |
| Good for | Fixed-choice classification, routing, rubric scoring, and guardrail judgments |
| Limits | Does not generate free-form text; probability is not correctness. Your code and Eval set thresholds, permissions, and fallbacks. 262K long context and images require separate opt-in; experimental, not defaults |
| Official source | TypeSafe model specs · Jev introduction · Early-access announcement · Cloudflare route · Image limits |
Gemini
| Field | Details |
|---|---|
| Models | Gemini 3.8 Flash |
Gemini 4 Argon (gemini-4-argon) | |
| Status | Flash/Argon: generally available. |
| Gemini 4 Carbon: Preview; phased access for selected partners, not a generally available API. | |
| Context | Flash: 1,048,576 context / 65,536 max output. |
| Argon: 1,048,576 combined input/output; default synchronous output 65,536. | |
| Carbon: input context and maximum output not published by the official source. | |
| Price or license | US$ per million tokens. Flash: $0.75/$3.75 input/output through 2026-12-31. |
| Argon Standard input/cache/output: $2/$0.10/$10 through 2026-11-30. $4/$0.20/$20 from 2026-12-01. | |
| Carbon announced introductory input/output: $2/$10. Cached input is 5% of the current input price ($0.10 during the introductory period). | |
| Carbon announced post-introductory input/output: $4/$20. The introductory end date has not been published. | |
| Good for | Flash for multimodal and Agent practice. Argon for comparing long tasks and coding outcomes. |
| Carbon is announced for sustained coding and computer-security defense; it is not yet a general beginner recommendation. | |
| Limits | Argon has no free tier. Output up to 1M requires long decode, not the default for every request. |
| Carbon API ID, tool support and general-access date have not been published. Announced pricing does not mean the API can be called now. | |
| This chapter still starts with local models. | |
| Official source | Gemini 3.8 Flash · Gemini API pricing · Gemini 4 Argon specs · Launch announcement |
| Carbon announcement and advertised pricing · General developer model list |
DeepSeek
| Field | Details |
|---|---|
| Models | V4.1 Flash 1017 (deepseek-flash) |
V4 Pro 0813 (deepseek-v4-pro) | |
| Status | Both APIs are officially available; Flash 1017 also has released weights. Old V4 Flash is retired. |
| Context | 1M context / 384K max output |
| Price or license | USD (US$) per million tokens; values below are peak/off-peak. Flash cache-miss input US$0.30/$0.15, output US$1.20/$0.60, and cache-hit input US$0.006/$0.003. Pro cache-miss input US$1.32/$0.66, output US$3.96/$1.98, and cache-hit input US$0.044/$0.022. Flash 1017 released weights are MIT; self-hosted hardware and runtime costs are separate. |
| Good for | Reasoning, coding, high-token workloads |
| Limits | The legacy Peak: Mon–Fri UTC 01:00–04:00 and 06:00–10:00. Chinese public holidays are not peak; other times are off-peak. Flash 1017 weights are a large model; do not treat them as a typical laptop starting point. |
| Official source | DeepSeek models and pricing · Changelog · Flash 1017 official weights |
Kimi
| Field | Details |
|---|---|
| Models | Kimi K3.1 Pro (kimi-k3.1-pro) |
Kimi K3.1 Pro Highspeed (kimi-k3.1-pro-highspeed) | |
| Status | Generally available API after a minimum US$1 top-up. Full weights are announced for 2026-11-04; do not treat them as downloadable yet. |
| Context | 1,048,576 tokens. |
| Price or license | International API, US$ per 1M tokens, input/cache read/cache write (5 minutes)/output; excluding taxes. |
| Pro $2/$0.20/$2/$10. | |
| Highspeed $4/$0.20/$4/$20. | |
| Repeated prefixes are cached automatically; 1-hour retention has separate write rates. API usage billing is separate from Kimi membership or Kimi Code subscriptions. | |
| Good for | Long coding tasks, images and video, and long-document work. Test your own tasks; vendor scores do not guarantee outcomes. |
| Limits | Thinking is always on. reasoning_effort supports low/high/max, default max. Preserve complete assistant messages in tool conversations. |
| K3 is the previous generation. K2-series access closes to new accounts on 2026-10-31; retirement is planned by the end of 2026, not already complete. | |
| Official source | K3.1 Pro guide · Models and migration · International API pricing · Billing guide · Cache billing |
Hunyuan
| Field | Details |
|---|---|
| Models | Hy3 (TokenHub) |
| Status | Generally available |
| Context | 256K |
| Price or license | API: CNY 0.25/1/4 per million tokens for cache hit/input/output |
| Good for | Chinese reasoning and Tencent Cloud integration |
| Limits | hy3-preview shut down on 2026-08-31; Hy4 remains Preview |
| Official source | TokenHub model list · TokenHub pricing · Hy3 migration notice |
MiniMax
| Field | Details |
|---|---|
| Models | MiniMax M3 |
| Status | Open weights |
| Context | 1M |
| Price or license | MiniMax API promotional price per million input/cache-read/output tokens: ≤512K US$0.30/$0.06/$1.20; 512K–1M US$0.60/$0.12/$2.40; MiniMax Community License |
| Good for | Text, vision, coding, and self-hosting work |
| Limits | Promotions and reseller prices may change; not Apache/MIT |
| Official source | MiniMax M3 model card · MiniMax API pricing |
Qwen
| Field | Details |
|---|---|
| Models | qwen3.8-max (API) |
| Qwen3.8 open-weight variants | |
| Status | Generally available |
| Context | 1M |
| Price or license | API pricing varies by region; for example, Beijing is CNY 12/36 per million input/output tokens; open-weight variants use their own licenses |
| Good for | Chinese tasks, multimodal work, self-hosted workflows |
| Limits | API models and open-weight variants must be checked separately for availability and license |
| Official source | Qwen 3.8 Max |
GLM
| Field | Details |
|---|---|
| Models | GLM-5.3 |
| Status | Generally available |
| Context | 1M (128K output) |
| Price or license | API: US$1.40/$0.26/$4.40 per million tokens for input/cache hit/output |
| Good for | Chinese agents, tool use, reasoning |
| Limits | Text-only; reasoning is always enabled |
| Official source | GLM-5.3 docs · GLM API pricing |
Yi
| Field | Details |
|---|---|
| Models | Yi-34B / Yi-9B and 200K variants |
| Status | Frozen / historical |
| Context | 200K (some older models) |
| Price or license | Repository license; current API price not published |
| Good for | Reproducing existing Yi experiments and historical self-hosted baselines |
| Limits | Repository does not establish current maintenance or a frontier successor |
| Official source | 01.AI Yi repository |
Llama
| Field | Details |
|---|---|
| Models | Llama 4 Scout / Maverick |
| Llama 3.3 70B (more practical older baseline) | |
| Status | Open weights |
| Context | Scout 10M |
| Price or license | Llama Community License |
| Good for | Self-hosting, fine-tuning, ecosystem integration |
| Limits | Scout needs H100-class hardware; license is not Apache/MIT |
| Official source | Meta Llama docs |
Muse
| Field | Details |
|---|---|
| Models | Muse Wonder (muse-wonder-1.0) |
Muse Spark 1.3 (muse-spark-1.3 / muse-spark-1.3-contributor) | |
| Muse Glimmer 30B | |
| Status | Wonder/Spark: available on API; Glimmer: open weights |
| Context | Wonder/Spark: 1,048,576; Glimmer: 131K |
| Price or license | Per million input/cache-hit/output tokens. Wonder Standard: US$4/$0.20/$20. Spark Standard: US$1.25/$0.15/$4.25. Spark Contributor: US$0.10/$0.002/$0.20, allowing Meta to train on content. Glimmer: Apache 2.0 |
| Good for | Wonder for comparing long tasks and multi-file coding. Spark for focused cloud tasks; Glimmer for local agents |
| Limits | Product Muse, API models, and open weights differ. Wonder API has no Contributor mode. Wonder Full requires specific Muse Code subscriptions, not max effort. Spark 1.3 audio support remains incomplete |
| Official source | Meta Model API models · Pricing and data plans · Muse Glimmer |
Grok
| Field | Details |
|---|---|
| Models | Grok 4.7 (grok-4.7) |
| Status | Generally available |
| Context | 500K |
| Price or license | xAI API: US$2/$0.50/$6 per million input/cache-hit/output tokens; when the prompt reaches 200K, the entire request uses US$4/$1/$12 |
| Good for | Coding, tool calls, and multi-step agents |
| Limits | US regional endpoints add 10%; server-side tool calls may cost extra |
| Official source | Grok 4.7 specs · xAI pricing |
MiMo
| Field | Details |
|---|---|
| Models | MiMo V2.6 Pro (mimo-v2.6-pro) |
| Status | Generally available API |
| Context | 1M context / 128K max output |
| Price or license | Xiaomi API: US$0.435/$0.0036/$0.87 per million input/cache-hit/output; also listed as CNY 3/0.025/6 |
| Good for | Long tasks, tool calls, and multimodal agent input |
| Limits | Confirm account region, quota, and billing; vendor benchmarks are not cross-model rankings |
| Official source | MiMo V2.6 Pro specs and pricing · MiMo API models |
Gemma
| Field | Details |
|---|---|
| Models | Gemma 4: E2B, E4B, 12B, 26B A4B, 31B |
| Status | Open weights |
| Context | 128K for small models; 256K for medium models |
| Price or license | Gemma 4 Terms/license; not Apache 2.0 |
| Good for | Edge, local use, constrained-hardware experiments |
| Limits | Read the license terms; hardware needs vary by model |
| Official source | Gemma core docs · Gemma Terms |
Mistral
| Field | Details |
|---|---|
| Models | Mistral Large 4 (mistral-large-4) |
Medium 3.5 (mistral-medium-3-5) | |
| Small 4 | |
| Large 3 | |
| Ministral 3 | |
| Status | Large 4: Public Preview. Medium 3.5/Small 4: generally available |
| Context | Large 4: 1M. Medium 3.5/Small 4: 256K |
| Price or license | US$ per million tokens. Large 4 input/cache/output: promotional US$0.68/$0.07/$2.09, list US$1.36/$0.14/$4.18. Medium 3.5 input/output $1.50/$7.50, Modified MIT. Small 4: $0.15/$0.60, Apache 2.0 |
| Good for | Compare reasoning, vision, coding, and tool use. For self-hosting, choose a model with released weights and license terms |
| Limits | Large 4 weights not yet released. Promotion lasts 2 weeks after launch, not a permanent rate. Do not treat the whole family as Apache 2.0 |
| Official source | Large 4 specs and pricing · Release status · Medium 3.5 · Small 4 |
Phi
| Field | Details |
|---|---|
| Models | Phi-4 14B |
| Phi-4 mini / multimodal | |
| Status | Open weights |
| Context | Phi-4 multimodal 128K |
| Price or license | Phi-4 multimodal MIT; check each model's license |
| Good for | Small-model reasoning, multimodal work, edge use |
| Limits | Do not assume fixed RAM; quantization changes hardware needs |
| Official source | Microsoft Phi · Phi-4 multimodal |
For an agent that listens and answers immediately by voice, optionally read Gemini 3.8 Live. It is a separate stable voice API model, not the Gemini 3.8 Flash listed above; check the Gemini API pricing page for cost and features.
API and decision-model electives: finish a standard request first, then compare what your task needs.
- Ultrafast (a paid lower-latency service tier): makes supported models respond faster; it is neither a new model nor free acceleration. The official guide covers GPT-6.1 Sol; pricing depends on the service tier.
- Decisions API (a judgment interface, generally available): asks
gpt-6-lunato classify, score, or estimate a probability from fixed answers. Each request allows up to 400 questions and does not execute tools. Standard cache-miss input is US$0.10 per million tokens, with no output-token charge. Check the official guide for caching, long-context, and regional surcharges; this is not the price of ordinary text generation. - Clef (a self-hostable decision model): gives text, images, and fixed choices a probability per answer; it does not write prose. Cloudflare's 27B weights use Apache-2.0. It is not a Jev model or a chat model. The official model card uses H200 hardware in its test environment, which does not guarantee an ordinary laptop can run it. This is optional reading, not a local-run test.
Neither score is permission to act. Test errors with your own cases, then have code check permissions; hand uncertain or high-risk cases to a person.
🧪 Supplementary explanation, troubleshooting, and personal evaluation tools
Why temperature changes output
At each step an LLM predicts a probability distribution for the next token, then chooses a candidate using its settings. Low temperature concentrates the distribution; high temperature gives less common candidates more chance. max_tokens is an output ceiling, not a promised length. This is a simplified mental model; behavior still depends on the provider's implementation.
Common problems
Connection refused: make sureollama serveis running and thebase_urlport is 11434.- Model not found: run
ollama list, then install withollama pull gemma4:e4b; do not guess a tag. - Truncated response: check
finish_reasonand the model's context window first. Iffinish_reason="length"and the answer is incomplete, modestly raisemax_tokensor shorten the requested answer; if the prompt and conversation history exceed the context window, shorten the input. - Ollama returns empty content or
finish_reason="length":max_tokenscaps one generation. In the reported setup (gemma4:e4bwith Ollama 0.34.2), thinking may consume this budget; both Path A examples setreasoning_effort="none"and accept onlyfinish_reason="stop"with nonblankcontent. This is evidenced only for that model/version; verify compatibility before changing either. This is a per-call output limit, not a paid API quota. - API failure: save the model, status code, and request id. Retry only temporary network/service errors; fix authentication and context errors first.
- Cost mismatch: multiply input and output separately; cache hits, batches, and plans can change the actual price.
Third-party benchmarks
Artificial Analysis, Arena AI, Vellum leaderboard, Hugging Face Open LLM Leaderboard, and SuperCLUE are tools for evaluating your task. They are not official provider specifications and cannot replace tests with your own data, prompts, and latency.
Self-Check
Before Stage 2, confirm that you can:
- Explain what API, token, and context window each do.
- Run Exercise 1's Ollama Path A and read output tokens from
usage. - Calculate one cloud-call cost from measured input/output tokens.
- Explain why you chose local or cloud for one scenario and name one limitation.
If yes, continue to Stage 2 — Prompt Engineering. If not, rerun Exercises 1–3 on Path A, then open the reading or troubleshooting sections as needed.
✅ Stage 1 complete? Stage 2 — Prompt Engineering will help you write reusable structured prompts and quantify improvements with evals.